Your AWS bill arrives, and for the second month in a row, it has climbed by double digits. Your finance dashboard confirms the total, but it offers no narrative. Was this increase triggered by a surge in genuine customer traffic, or is a misconfigured autoscaler burning through your budget? Did a specific deployment three days ago cause a memory leak that forced your infrastructure to scale indefinitely?
For many engineering organizations, the current state of cloud financial management (FinOps) is stuck in a reactive loop: a bill arrives, costs are higher than expected, and the engineering team is forced into a manual, time-consuming investigation to identify the "why." This guide provides a framework for navigating the complex landscape of AWS cost management tools, helping you distinguish between platforms that merely report spend and those that provide the operational context required to take action.
Main Facts: The Intersection of Engineering and Finance
Cloud cost management has evolved from a back-office accounting task into a critical engineering discipline. Today, engineers make the daily architectural decisions—resource limits, instance types, autoscaling thresholds, and deployment frequencies—that directly dictate the monthly bill.
However, native billing data is increasingly disconnected from the realities of modern infrastructure. In a containerized or serverless environment, a single line item on an AWS invoice can represent the shared work of dozens of microservices. When spend rises, the finance team often sees only the aggregate, leading to meetings that focus on blame rather than technical resolution.
The core challenge is "attribution under pressure." To effectively manage costs, organizations must move beyond the "what" (total spend) and gain visibility into the "why" (system behavior).
Chronology of Cost Complexity
To understand why traditional cost tools are failing, one must look at how cloud environments have evolved:
- The Monolithic Era: In the early days of cloud, one EC2 instance often served one application. Billing reports were simple to reconcile.
- The Rise of Shared Infrastructure: With the advent of Kubernetes and serverless (AWS Lambda), compute resources are now shared across hundreds of workloads. A single node might host components from three different product teams, making flat billing data virtually useless for internal showback.
- The AI/ML Complexity Spike: According to Flexera’s 2026 State of the Cloud Report, organizations now estimate that 29% of their cloud spend is wasted. This figure, which has risen for the first time in five years, is driven by the rapid deployment of resource-intensive AI models and new, high-cost cloud services that often lack granular usage transparency.
- The Observability Shift: Modern organizations are now realizing that cost is a form of telemetry. Just as you monitor CPU and latency, you must now monitor the "cost-per-request" or "cost-per-deployment" to understand the fiscal health of your software.
Supporting Data: The Cost Management Ecosystem
The market for cloud cost management tools is divided into four distinct categories: Observability-led, Unit-economic-focused, Automation-heavy, and Governance-first.
Comparative Analysis of Leading Platforms
| Tool | Primary Strength | Best For | Telemetry Integration |
|---|---|---|---|
| New Relic | Cost-to-Telemetry Correlation | DevOps/Engineering | Native |
| CloudZero | Unit-Economics/Business KPIs | FinOps/Product Teams | Limited |
| ProsperOps | Autonomous Discount Mgmt | Hands-off Ops | None |
| nOps | Kubernetes Rightsizing | K8s-Heavy Teams | Partial |
| Ternary | Multi-Cloud Governance | Enterprises/MSPs | Limited |
Native AWS Tooling: The Baseline
AWS provides a solid foundation with tools like Cost Explorer, Budgets, and the Cost and Usage Report (CUR). These are essential for initial visibility. However, they are inherently limited because they lack "application awareness." They can tell you an EC2 instance is expensive, but they cannot tell you that it is expensive because of a specific buggy deployment that occurred on Tuesday at 2:00 PM.
Official Perspectives: The Industry Divide
The industry is currently split on whether cost management should live within the Finance department or the Engineering department.
The FinOps Foundation’s Perspective: The FinOps Foundation advocates for a cross-functional culture where engineers take ownership of their cloud usage. This requires "showback" or "chargeback" models, where teams see the direct impact of their architectural decisions on the bottom line.
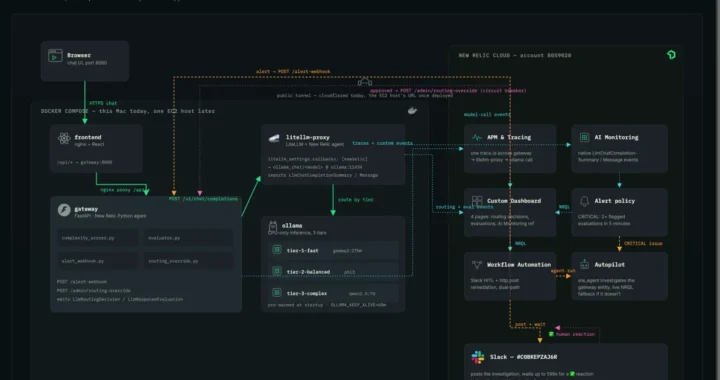
The Observability Perspective: Advocates of observability, such as those at New Relic, argue that forcing engineers to switch between a monitoring tool (like Datadog or New Relic) and a finance tool (like CloudZero or Ternary) creates "context friction." They argue that by embedding cost data directly into the observability workflow, developers can treat cost anomalies just like performance anomalies—identifying, investigating, and fixing them in a single pane of glass.
Implications for Modern Organizations
The decision to choose a specific tool has deep implications for how your engineering organization operates.
1. The Cost of Context Switching
If you choose a platform that optimizes spend in isolation (e.g., automated commitment management), you may save on your monthly bill, but you will still face the same "why did this spike?" questions every time a deployment goes wrong. Your team will spend hours manually correlating Jira tickets with AWS billing timestamps.
2. The Power of Unit Economics
For product-led organizations, understanding "cost per customer" is the ultimate goal. Platforms like CloudZero are built specifically for this. If your primary goal is to understand how much profit you make on a per-customer basis, investing in granular allocation tools is more important than investing in real-time infrastructure observability.
3. The Automation Trap
Autonomous tools like ProsperOps or nOps offer significant "low-hanging fruit" savings by managing Reserved Instances and Savings Plans. However, these tools are not replacements for good engineering. They can optimize your rates, but they cannot fix an inefficient, bloated, or poorly designed application architecture.
Strategy: How to Choose the Right Path
When shortlisting your next cost management tool, follow this three-step strategic framework:
Step 1: Identify your immediate pain point.
Are you overpaying for commitments (e.g., unused RIs)? If yes, start with ProsperOps. Are you struggling with runaway Kubernetes costs and don’t know which team is responsible? Look at nOps or Ternary. Are you tired of "ghost" cost spikes that your on-call team cannot explain? You need an observability-centric approach like New Relic.
Step 2: Assess your organizational maturity.
If your team lacks consistent resource tagging, no tool will save you. The "garbage-in, garbage-out" rule applies heavily here. Before investing in expensive third-party platforms, ensure your internal account structure and tagging conventions are robust.
Step 3: Evaluate the integration gap.
Ask yourself: Where does my team spend their day? If your developers are already deeply embedded in an observability platform, adding a cost-intelligence layer to that existing tool will likely lead to higher adoption rates than introducing a standalone financial dashboard that developers rarely check.
Conclusion: The Path Forward
The future of cloud financial management is not about "saving money" in a vacuum; it is about "operational visibility." The most successful engineering teams are those that can trace a spend change back to a specific service behavior, deployment, or infrastructure event with the same ease that they debug a system failure.
By choosing a tool that aligns with your specific operating model—whether that is autonomous discount management, granular unit-cost accounting, or integrated observability—you move from being a passenger on the AWS billing roller-coaster to being the operator of your cloud budget.
If you are currently experiencing high-friction investigations, the answer is likely not more reports, but better data. Start by identifying the telemetry gaps in your current stack, and prioritize a platform that bridges the divide between what your systems are doing and what those systems are costing.
Frequently Asked Questions
Why is Kubernetes cost visibility harder than traditional infrastructure?
In a traditional EC2 environment, costs are tied to specific instances. In Kubernetes, the "bin-packing" of pods means many services share the same underlying nodes. Without a tool that can map container-level resource requests and limits back to namespaces and labels, you are essentially looking at an aggregate lump of compute costs without knowing which team or application caused the usage.
How often should engineering teams review cost anomalies?
Anomaly alerts should be treated with the same urgency as critical system outages. A misconfigured autoscaler caught on the same day costs pennies compared to one that runs for 30 days. For rightsizing and architectural optimization, a quarterly cadence is typically sufficient, but operational anomalies demand real-time attention.
What makes cloud cost attribution difficult in multi-account environments?
Shared services, cross-account data transfers, and inconsistent tagging across large organizations often create "unallocated spend." When you cannot map a dollar spent to a specific business unit, your FinOps efforts will fail because you cannot hold the correct stakeholders accountable. Clean metadata is the mandatory prerequisite for all cost management success.